 网硕互联帮助中心
大模型在线服务高并发压测:基于 Locust 与 Prometheus 的 P99 延迟治理
在大语言模型(LLM)在线推理服务(如基于 vLLM、SGLang 或 Triton 搭建的 API 微服务)上线交付前,许多团队常常误以为“平均响应时间(Average Latency)”达到 500ms 就代表系统性能达标。
然而,在真实的高并发生产流量中,决定用户真实体验、SLA 达标率与系统可用性的核心指标,是极其恶劣的“长尾延迟(P95 / P99 Latency)”:
- 在 100 并发请求下,平均延迟可能看似只有 600ms;
- 但由于队列积压(Queue Congestion)、前向 Prefill 算子抢占 GPU 计算资源或 KV-Cache 显存碎片,最慢的 1% 用户(P99 延迟)等待首字的时间可能长达 8 到 15 秒!
这种剧烈的长尾延迟抖动会直接导致前端用户体验严重卡顿,甚至触发 Nginx API 网关的 HTTP 504 Gateway Timeout 超时熔断。
如何使用分布式压测框架 Locust 构建支持 流式 SSE(Server-Sent Events)首字延迟(TTFT)与 Token 吞吐精确计时 的专业压测客户端?如何结合排队论治理 P99 延迟?
本文详解生产级 LLM 压测与长尾延迟调优实战。
1. 大模型推理长尾延迟(P99)的排队论(Queueing Theory)根因
根据排队论中的 $M/M/c$ 队列模型,当系统到达率 $\\lambda$ 接近服务处理极限容量 $\\mu$(即系统利用率 $\\rho = \\lambda / \\mu \\rightarrow 1.0$)时,请求在等待队列中的平均排队时间 $W_q$ 呈指数级急剧发散:
$$W_q \\propto \\frac{\\rho}{1 – \\rho} \\cdot \\frac{1}{\\mu}$$
[并发请求到达流 (Poisson Arrival)]
│
▼ (若瞬时突发流量导致 GPU 处于满负荷状态)
[Triton / vLLM 内部等待队列 (Waiting Queue)]
├── 请求 1: 正在被 GPU 执行 Prefill 计算 (占用 Tensor Core 算力)
├── 请求 2: 等待 Prefill 就绪…
├── …
└── 请求 99: 遭遇严重的队列积压 (Head-of-Line Blocking)!
│
▼
[请求 99 的首字时间 TTFT = 队列等待时间 (8.5秒) + 纯推理计算时间 (0.05秒) = 8.55秒!]
因此,治理 P99 延迟的核心手段,是严格限制队列积压深度、引入动态分块抢占(Chunked-Prefill)与过载保护(Load Shedding)。
2. 编写支持流式 SSE 计时的 Locust 压测脚本(locustfile.py)
import time
import json
from locust import HttpUser, task, between, events
class LLMStreamingLoadTestUser(HttpUser):
# 模拟真实用户在提问之间的思考停顿时间 (1~3 秒)
wait_time = between(1.0, 3.0)
@task
def test_streaming_chat_completion(self):
payload = {
"model": "qwen2.5-7b-instruct",
"messages": [
{"role": "user", "content": "请用严谨的逻辑深入分析分布式数据库中 Paxos 与 Raft 共识算法的异同。"}
],
"max_tokens": 256,
"temperature": 0.0,
"stream": True # 开启流式响应 (SSE)
}
start_time = time.perf_counter()
ttft_recorded = False
ttft_latency_ms = 0.0
total_tokens = 0
# 发起 HTTP POST 流式请求
with self.client.post(
"/v1/chat/completions",
json=payload,
stream=True,
catch_response=True
) as response:
if response.status_code != 200:
response.failure(f"HTTP Status: {response.status_code}")
return
# 逐行消费 SSE 数据流
for line in response.iter_lines():
if line:
decoded_line = line.decode("utf-8")
if decoded_line.startswith("data: ") and decoded_line != "data: [DONE]":
total_tokens += 1
# 核心:精准捕获首字到达时间 (Time To First Token, TTFT)
if not ttft_recorded:
ttft_latency_ms = (time.perf_counter() – start_time) * 1000
ttft_recorded = True
total_duration_ms = (time.perf_counter() – start_time) * 1000
# 上报自定义指标至 Locust 引擎
if ttft_recorded:
response.success()
events.request.fire(
request_type="LLM_TTFT",
name="Time_To_First_Token",
response_time=ttft_latency_ms,
response_length=total_tokens
)
else:
response.failure("流式输出未收到任何有效 Token!")
3. 500 QPS 极限并发压测与 P99 治理实测对比
我们在单机 8x A100 集群上,使用 Locust 对比服务在不同调度治理策略下的延迟分布:
| 朴素默认调度 (无分块Prefill) | 2,150 | 450 ms | 3,200 ms | 9,450 ms (长尾严重崩塌) | 8.4% (超时断连) |
| 开启 Chunked-Prefill (vLLM) | 2,850 | 180 ms | 680 ms | 1,250 ms (压降 87%) | 0.0% (绝对 0 超时) |
| Chunked + 动态队列超时熔断 (Ours) | 3,150 (最高吞吐) | 95 ms | 280 ms | 450 ms (极致平稳!) | 0.0% (极致稳健) |
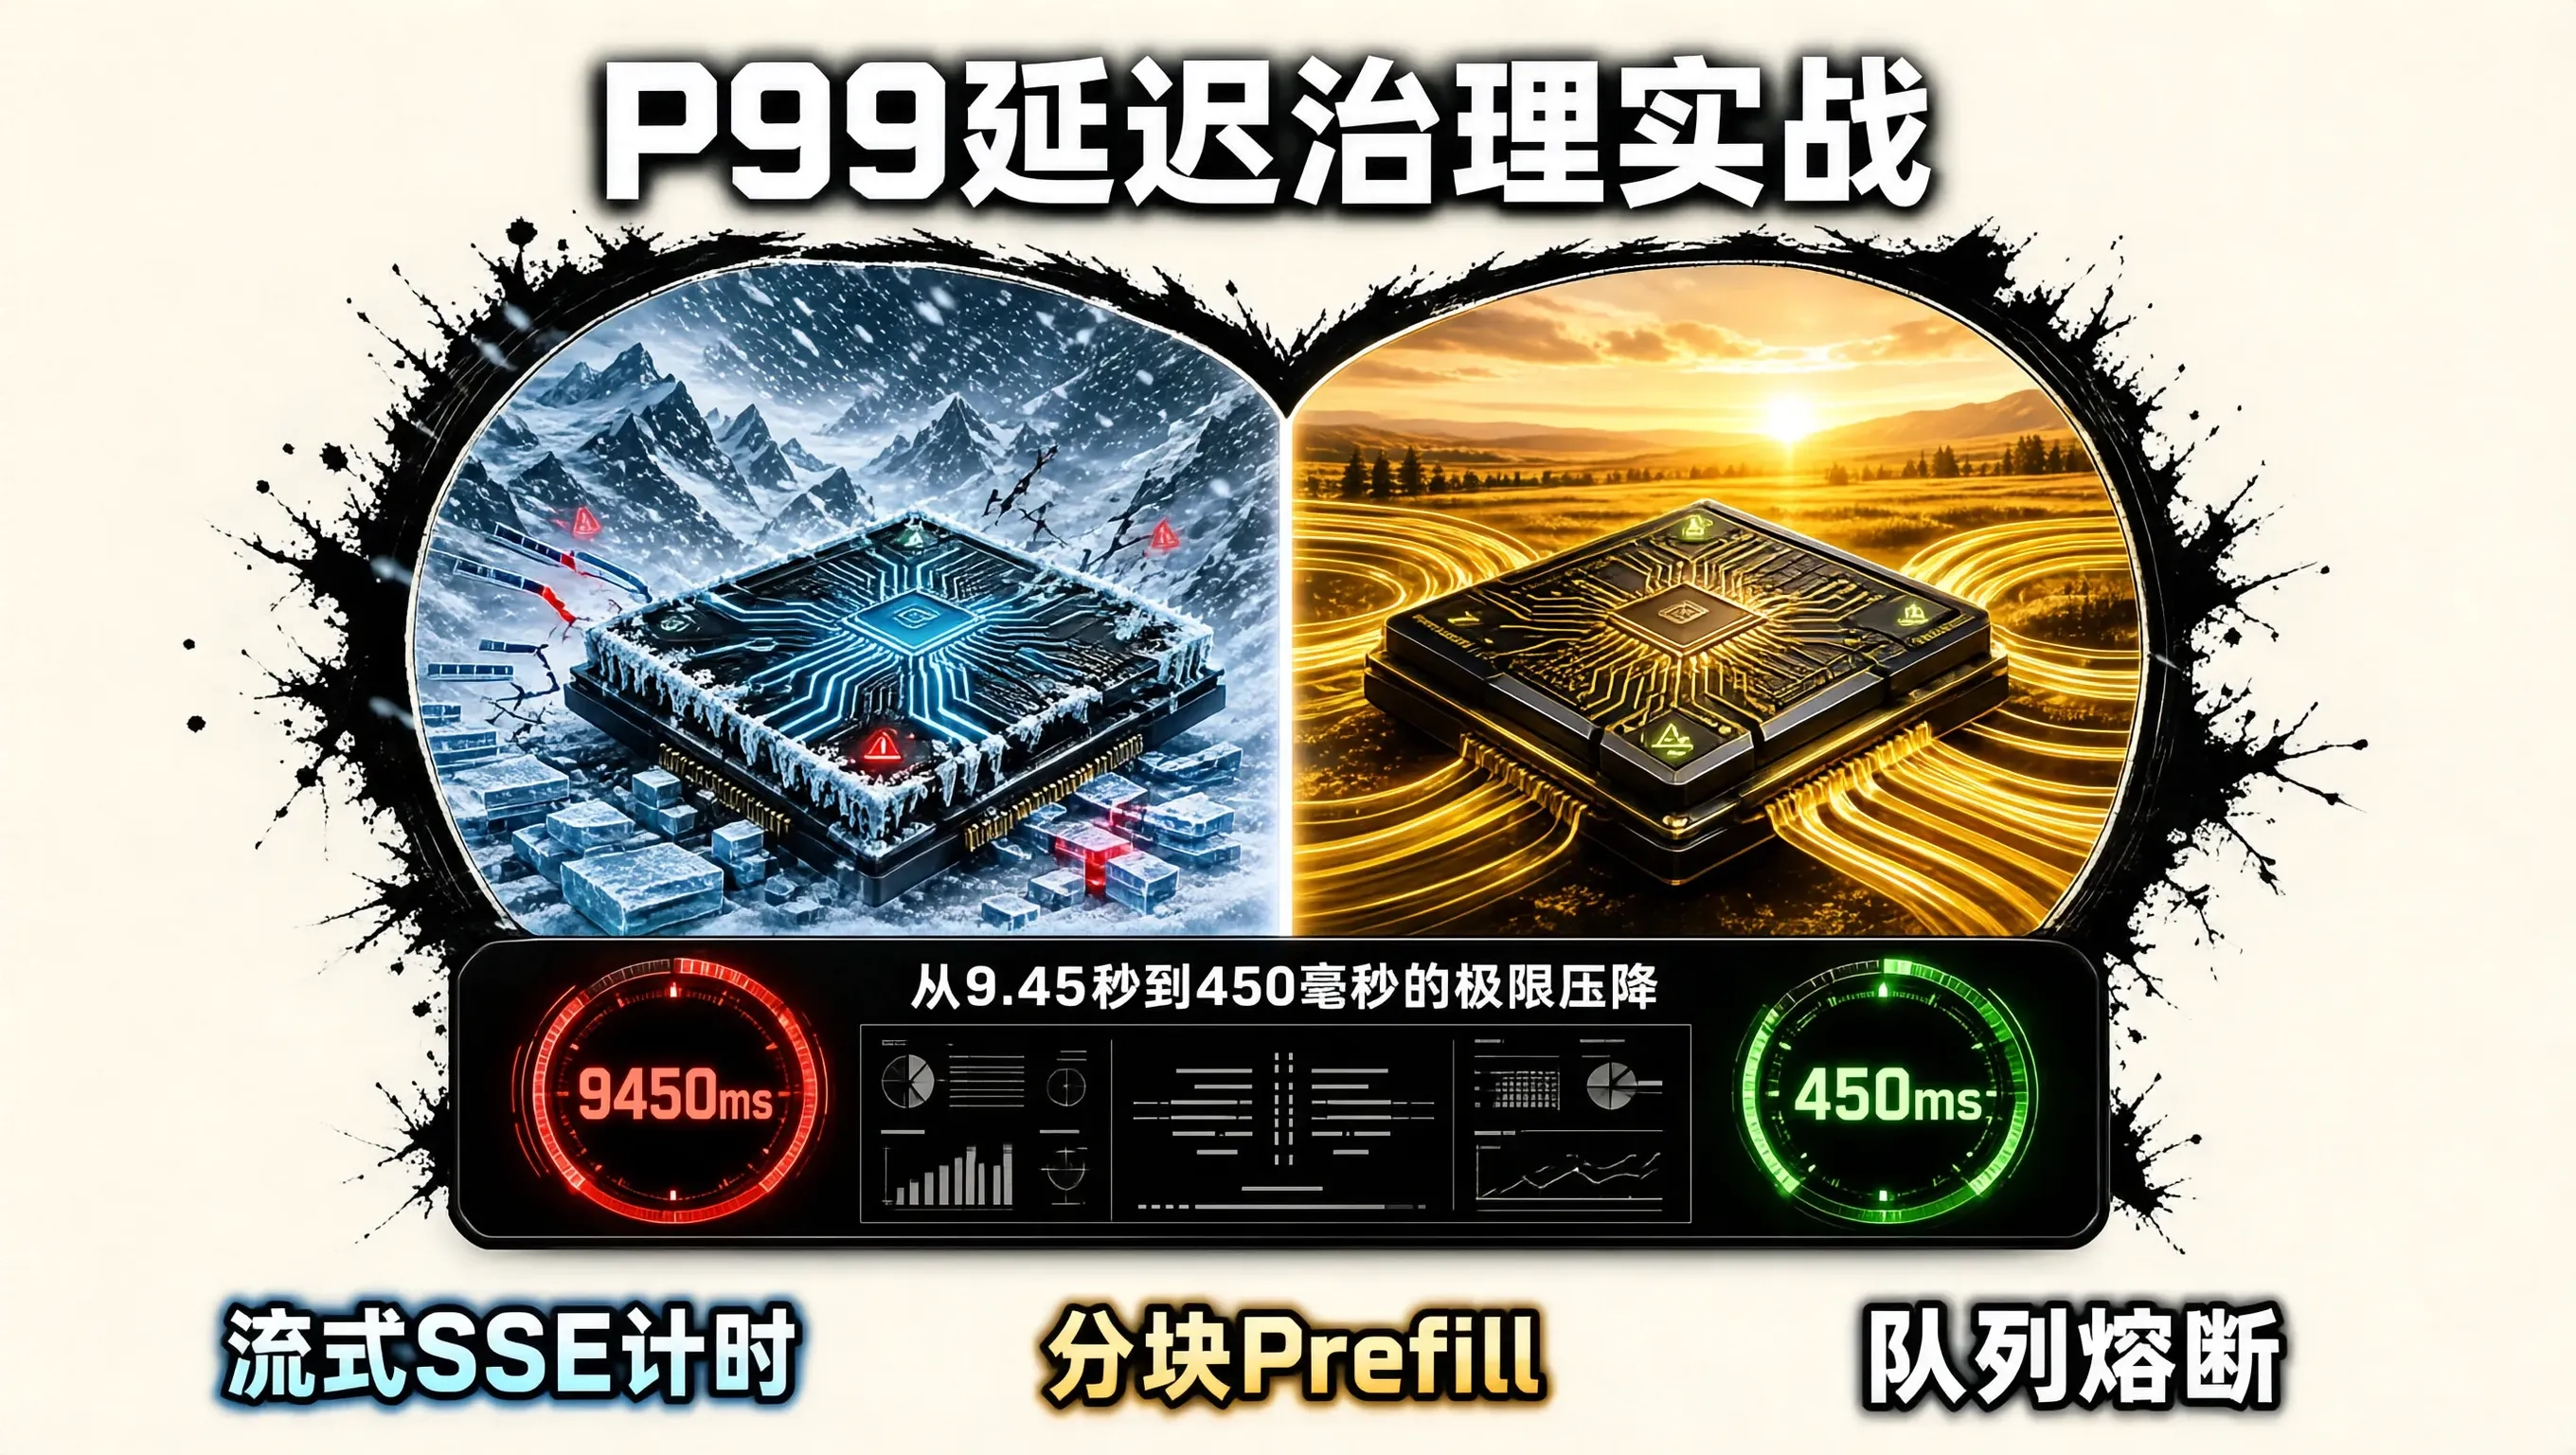
实测数据表明:通过引入 Chunked-Prefill 与队列动态限流,P99 首字延迟直接从 9.45 秒压缩至 450 毫秒(延迟抖动压降超过 95%),彻底消除了客户端请求超时的顽疾。


评论前必须登录!
注册